Chapter 2.1 — Models & the Intelligence Frontier
Better models do not automatically create a better model business. Capability leadership changes quickly, open systems compress price, and inference turns intelligence into a recurring cost on every query. The investor's problem is to decide whether cheaper intelligence expands usage fast enough to reward the infrastructure below it—and whether any model provider can keep the resulting profit.
Model demand drives spending on power, memory, data centers, and accelerators. A foundation model is a large neural network trained on a broad body of text, code, or images. Its compute use has two distinct forms. Pre-training is the large initial run that builds patterns into billions of parameters. Inference consumes compute each time a user or application asks the model to produce output. Pre-training is concentrated in model-development cycles; inference recurs with every query. Their relative growth changed in 2025, with inference becoming the larger source of ongoing demand.
Start with one model call
A user types, “Review this contract and identify the clauses that could create liability.” The visible result may arrive in seconds, but the economic transaction is more complicated. The application sends the contract and instructions to a model. The model reads the context, produces intermediate reasoning, may retrieve reference material or call another tool, and generates an answer token by token. The provider pays for accelerators, memory, network capacity, electricity, and cloud or owned infrastructure during that process.
If the answer is short and the model is small, the cost can be tiny. If the task uses a frontier reasoning model, a long document, repeated tool calls, and several attempts to verify the result, the invisible computation can be many times larger than the text the user sees. The customer may pay through a monthly subscription, an application vendor may pay an API fee, or a large enterprise may negotiate a dedicated-capacity contract. The model company keeps only what remains after infrastructure and distribution costs.
This simple call exposes the chapter’s four linked questions. How much computation does a useful answer require? How quickly is the price of that answer falling? Does lower price create enough new usage to increase total spending? And can one provider keep the customer when several models offer similar quality? The first three determine aggregate demand for the physical stack. The fourth determines whether that demand produces a durable model-company moat.
Efficiency by itself is therefore neither bullish nor bearish for infrastructure. Suppose the cost of one task falls by 80%. If customers perform the same number of tasks, spending falls. If lower prices bring ten times as many tasks into production, spending rises despite the efficiency gain. If those tasks also become longer-running agents, compute can rise faster still. The variable that connects model progress to the rest of the atlas is demand elasticity—how strongly usage responds when intelligence becomes cheaper and more capable.
Why model progress has not automatically become a moat
For most of the past decade the business ran on a rule reliable enough to underwrite the entire boom: enlarge the model, add data, and it improves at a predictable rate. Through 2025 that rule bent, and the people best placed to see it said so plainly. Ilya Sutskever, who coined the phrase "data is the fossil fuel of AI" at NeurIPS in December 2024, described in a November 2025 interview the close of "the age of scaling" and the opening of an "age of research," where the bottleneck is ideas rather than compute. The products bore him out. OpenAI's GPT-5, released on 7 August 2025, was widely read as a refined packaging of existing capability — a router unifying older models with reasoning modes — rather than a generational leap.
The frontier did not stall; it changed axis. The newest systems improve by reasoning at the moment of use, generating long internal chains of thought before they answer, rather than front-loading all their intelligence into a larger pre-trained model. Google's Gemini 3 Pro, released 18 November 2025, drew its reasoning edge explicitly from inference-time "Deep Think" rather than a bigger base model. xAI's Grok 4 was trained with reinforcement learning "at pre-training scale." The economic consequence is the point: a reasoning model can burn ten to a hundred times more tokens on a single query than a plain chatbot reply, and it does so on every use rather than once in training. Epoch AI put inference above 60% of total compute among the major providers by early 2025, and the share has climbed since; industry estimates put 80–90% of compute dollars on inference. When a later chapter tells you power has become the binding constraint, the cause traces back here.
There is a genuine debate underneath this. The bears — Sutskever, Gary Marcus — argue that each compute doubling now yields shrinking gains, and that knowledge benchmarks flatten past a certain scale. The bulls counter that a new scaling axis opened with its own reliable curve, so the frontier keeps moving; Gemini 3's strength is their exhibit. For an investor the resolution matters less than the direction: whichever camp is right, the compute intensity per query is rising, not falling.
Old benchmarks stopped discriminating just as inference became the new frontier
One visible symptom of the shift is that the old benchmarks stopped telling the models apart. MMLU-Pro sits saturated at 88–94% across every frontier model; AIME competition math runs 95–100%, with at least one model reported at a perfect score; GPQA-Diamond graduate science is near-saturated around 87–94%, above the ~70% human-expert baseline. When every leading model scores in the nineties, the benchmark no longer discriminates, so the industry has moved to a new generation of harder tests: autonomous-coding suites (SWE-bench Verified, Terminal-Bench), the deliberately brutal Humanity's Last Exam, the abstract-reasoning ARC-AGI-2, and the crowd-voted LMArena.
Even these are climbing fast. Humanity's Last Exam, designed to be near-impossible, has frontier models above 50%. ARC-AGI-2, on which every frontier model scored roughly 0% at its March 2025 launch, had leaders in the eighties within a year. The practical consequence is that benchmark leadership is now both fast-moving and hard to verify — the newest model names change monthly and many quoted scores come from aggregator sites of uncertain reliability — so the honest way to read the leaderboard is as a snapshot of a close race rather than a settled order.
The providers are competing with different economic models
Before ranking the models, it helps to know the roster, because these are the names that fill the headlines and earnings calls. The families worth recognizing, and who makes them:
| Model family | Maker | Country | Known for | Access |
|---|---|---|---|---|
| GPT-5.x | OpenAI | US | the consumer default; strong coding | PVT (via Microsoft) |
| Claude (Opus/Sonnet/Haiku) | Anthropic | US | enterprise & coding leader | PVT (via Amazon, Google) |
| Gemini 3 | Google DeepMind | US | multimodal + reasoning; Search/Workspace reach | GOOGL |
| Grok 4 | xAI | US | real-time, X-integrated | PVT (in SpaceX) |
| Llama 4 | Meta | US | open-weight pioneer (now retreating) | META |
| DeepSeek V4 / R-series | DeepSeek | China | the efficiency shock; open | PVT |
| Qwen 3 | Alibaba | China | most-downloaded open family | BABA / 9988.HK |
| Kimi (K-series) | Moonshot AI | China | long-context; open | PVT |
| GLM | Zhipu AI | China | open, enterprise | PVT |
| Ernie | Baidu | China | free consumer assistant | BIDU / 9888.HK |
| Hunyuan / Yuanbao | Tencent | China | super-app distribution | 0700.HK |
| Doubao | ByteDance | China | #1 China consumer app (382M MAU) | PVT |
| MiniMax / Hailuo | MiniMax | China | agents & video | PVT |
| Mistral / Magistral | Mistral AI | France | Europe's open-weight champion | PVT |
| Command | Cohere | Canada | enterprise retrieval | PVT |
| (no product yet) | Safe Superintelligence (SSI) | US | Sutskever's "age of research" bet | PVT |
| (no product yet) | Thinking Machines Lab | US | Mira Murati's lab | PVT |
Three patterns fall out of the roster. The closed frontier is a handful of US labs. The open-weight world is increasingly Chinese, and it is a crowded field — Alibaba, DeepSeek, Moonshot, Zhipu, MiniMax, and the big platforms (Baidu, Tencent, ByteDance) all ship competitive models. And two of the best-funded new labs, Sutskever's SSI and Murati's Thinking Machines, have no product at all, betting that the next breakthrough comes from research rather than from scaling what exists.
Three scoreboards are more useful than one champion
Ask "which model is best" and the honest answer is that it depends which scoreboard you read, and the three that matter give three different answers.
On raw capability, the race is close and reshuffles almost monthly. At the 25 July 2026 evidence cutoff, Anthropic's Claude family tops the general-ability and composite-intelligence leaderboards, while OpenAI's GPT-5-series leads autonomous coding.
| Scoreboard (observed by 25 July 2026) | Leader | Level | Source |
|---|---|---|---|
| General ability — LMArena Elo | Anthropic Claude family | ~1500–1507 | arena.ai (live) |
| Composite — Artificial Analysis Intelligence Index | Claude (Opus tier) | ~61 (of ~100) | Artificial Analysis |
| Hardest expert exam — Humanity's Last Exam | Claude family | ~53% | Artificial Analysis |
| Autonomous coding — SWE-bench Verified | OpenAI GPT-5.x | ~96% | aggregator estimate |
| Coding agents — Terminal-Bench 2.0 | GPT-5.5 harnesses | ~85% | tbench.ai |
| Graduate science — GPQA-Diamond | near-saturated (Grok-4 87% verified) | ~87–94% | Epoch AI |
Leaderboards move week to week; treat the ranking as a close race, not a fixed order. Aggregator-sourced scores are labeled in the table.
The second scoreboard is enterprise money, and it tells a cleaner, more durable story. Menlo Ventures' 2025 enterprise survey put Anthropic at 40% of enterprise LLM API spend, OpenAI at 27%, and Google at 21% — the top three taking 88% of a market where foundation-model APIs captured $12.5B of $18B in infrastructure spend, and where total enterprise AI spend hit $37B, up 3.2× year on year.1

The reversal is the headline: OpenAI held roughly 50% of this market in 2023 and Anthropic 12%. In coding specifically, Anthropic's lead is wider still, near 54% against OpenAI's 21%, up from 42% just six months earlier. Enterprises, in other words, increasingly pay Anthropic even as consumers overwhelmingly use OpenAI — a split that is central to how you value each lab.
Which is the third scoreboard: consumer reach, where OpenAI's lead is enormous.
| Consumer product | Active users | As-of | Source |
|---|---|---|---|
| ChatGPT | 900M weekly | 27 Feb 2026 | OpenAI2 |
| Google Gemini app | 750M monthly (+ AI Overviews ~2B) | Feb 2026 | TechCrunch |
| Meta AI | ~1B monthly | 2026 | company estimate |
| Grok | ~117M monthly (from 35M Dec-25) | Mar 2026 | reported estimate |
| DeepSeek (China) | 81.6M weekly | Feb 2026 | Reuters |
ChatGPT's more than 900M weekly actives, announced by OpenAI in February 2026, dwarf every rival. The three scoreboards resolve into a clean picture: OpenAI owns the consumer surface and the mindshare, Anthropic owns the enterprise wallet and the coding workflow, and Google owns distribution through Search and Workspace. None owns "the best model" for longer than a release cycle.
Open models are globalizing price competition
The scoreboard most investors miss is the developer one, and it has moved against the United States. On OpenRouter, a large model-routing marketplace, models of Chinese origin carried roughly 46% of identified tokens by June 2026 against about 36% for US-origin models, and open-weight models overtook proprietary ones to roughly a 60/40 split. DeepSeek was the single largest provider on the platform.

The trajectory is the striking part: US-model token share on the platform fell from around 70% in June 2025 to roughly 30% a year later. On Hugging Face, Alibaba's Qwen passed 700M downloads by January 2026, became the most-downloaded open family, and spawned more fine-tuned derivatives than Google and Meta combined; by one count Qwen derivatives were over 40% of all new language-model variants. These are aggregator figures and the exact percentages will move, but the direction is unmistakable and corroborated across sources.
This is strategy, not accident. Denied the best training silicon, China made openness an asymmetric weapon: a capable model anyone can download and run cheaply spreads Chinese technical influence, undercuts the pricing power of the American closed labs, and grows an ecosystem that needs no one's permission. DeepSeek's arrival in early 2025 briefly erased hundreds of billions in US AI market value precisely because it questioned the premise that compute scarcity was a durable moat. There is a wrinkle worth flagging: reports in 2026 that both Meta (pausing open Llama) and Alibaba (moving flagship Qwen toward closed) are partially reversing their open strategies, which, if it holds, would reshape this dynamic — treat it as developing.
Falling prices make demand elasticity the decisive variable
The reason the model layer is a hard place to make money is that the thing it sells is deflating faster than almost any product in history. Stanford's AI Index found the cost of GPT-3.5-level inference fell more than 280× between late 2022 and late 2024, from about $20 to about $0.07 per million tokens.3 Epoch AI's work on frontier pricing finds the cost to reach a fixed capability level fell between 9× and 900× per year across specific milestones, while warning that the fastest recent declines may not persist.4 Anthropic launched Claude Opus 4.5 in November 2025 at roughly a 67% price cut to its predecessor; Chinese labs cut prices around sixfold in the first half of 2026, declaring several cuts permanent.

The live spread makes the commoditization concrete: frontier-closed output runs roughly 5× to 100× the price of the leading Chinese-open models for capability that, on many tasks, is within a release cycle. Alongside the price collapse, the models have grown vastly more capacious: one-million-token context windows became generally available on the frontier models in 2026, with some pushing toward two million and Meta's Llama 4 Scout advertising ten million, though independent tests show effective context is closer to 50–65% of the advertised figure.
The central investment question in this layer is whether cheaper compute shrinks total spending or expands it. Current evidence favors expansion: efficiency improves rapidly, but usage has grown faster, so aggregate compute and capital spending continue to rise even as the cost of a query falls. That relationship is an observed regime, not a physical law. A large efficiency shock or slower usage growth would test whether deflation reaches infrastructure suppliers rather than remaining concentrated in model margins and token pricing.
Revenue still has to outrun the capital consumed
The valuations attached to this layer price a future the revenue has not yet reached, though the revenue is growing fast.

OpenAI's annualized revenue crossed roughly $20B during 2025 and stood at about $21.4B at year-end per Epoch AI's dataset, tracking toward a ~$30B target for 2026, against reported losses near $14B a year and a private valuation of $852B set in a $122B round in March 2026, with a confidential IPO filing reported for mid-2026. Anthropic's run-rate went from roughly $9B at the end of 2025 to over $47B by May 2026, on which it raised at a $965B valuation, the first challenger to exceed OpenAI's mark. xAI reported about $818M in the first quarter of 2026, roughly a $3.3B run-rate, against a $2.47B operating loss, and was valued at $250B inside SpaceX after an all-stock merger.
Anthropic provides strong evidence that deep technical workflows can monetize. Claude Code grew from a $500M run rate in September 2025 to more than $2.5B by February 2026, passed 2M weekly active users, and had more than 500 customers spending over $1M a year by April 2026. Coding therefore anchors the demand analysis in Chapter 2.2. Private valuations should still be read as negotiated, illiquid marks with liquidation preferences rather than as directly comparable market capitalizations. Listed backers offer indirect exposure, but their other businesses and entry valuation can dilute the connection.
A release lead is perishable
The pace of releases is itself a feature of this layer, and a strain on everything beneath it. The cadence over the past year:
| Date | Release |
|---|---|
| Aug 2025 | OpenAI GPT-5; gpt-oss-120B/20B (OpenAI's first open-weight in six years) |
| Sep 2025 | Anthropic Claude Sonnet 4.5; DeepSeek V3.2 |
| Oct 2025 | Anthropic Claude Haiku 4.5 |
| Nov 2025 | OpenAI GPT-5.1; Google Gemini 3 Pro + Deep Think; Anthropic Claude Opus 4.5 (−67% price) |
| Dec 2025 | OpenAI GPT-5.2 |
| Apr 2026 | GPT-5.4; Gemini 3.1 Pro; DeepSeek V4 ("near-frontier, a fraction of the price") |
| May 2026 | OpenAI GPT-5.5; Anthropic Claude "Mythos" preview |
| Jun–Jul 2026 | Claude Sonnet 5; further reported or roadmap releases from Claude, GPT-5.6, Grok 4.5, and Kimi K3 |
Meta's Llama 4 (Scout and Maverick) shipped, but its flagship "Behemoth" was effectively shelved, never formally released or cancelled. The relentless roughly-quarterly cadence is why benchmark leadership is so fleeting, and why the strain on the supply chain beneath — the chips, packaging, and power of later chapters — never lets up.
For agents, continuous correctness matters more than the demo
The product story of 2026 is agents — models that take actions over long horizons rather than only answering — and the early revenue is genuine. But this is the layer's clearest example of capability outrunning dependability.
Capability is improving faster than almost anywhere in AI. METR, which measures the length of task an agent can complete at 50% reliability, estimates that its broad historical horizon doubled roughly every seven months over the six years through 2025. Newer domain-specific slices can imply faster rates, but the estimate is sensitive to the task mix; METR explicitly warns that measurements beyond sixteen hours exceed the reliable range of its current suite.5 Anthropic's Model Context Protocol, an open standard for connecting agents to tools, was donated to the Linux Foundation and adopted by OpenAI, Google, and Microsoft, a genuine interoperability milestone.
The catch is reliability, not capability. A step that is 95% reliable, compounded across a long task, fails too often for production. MIT's Project NANDA found roughly 95% of enterprise generative-AI pilots delivered no measurable profit-and-loss impact; by most estimates 86–88% of agent pilots never reach production; and Gartner projects that more than 40% of agentic-AI projects will be canceled by the end of 2027 on cost, unclear value, and inadequate controls. Amazon's own AGI director stated flatly that it is agent reliability, not capability, that keeps enterprises in pilot. The gap between a demo that works most of the time and a system a business can trust with unattended work is where the next wave of value, and a new tooling layer built to make agents dependable, will be won. This is the same reliability gate that Chapter 2.2 treats from the application side.
Video and robotics widen the compute bill before they prove a business
The models layer is expanding sideways as fast as it is advancing, and a whole roster of companies sits in these adjacent frontiers. Video generation matured into a production tool over 2025–26: OpenAI's Sora, Google's Veo, Kuaishou's Kling and ByteDance's Seedance in China, and MiniMax's Hailuo now produce short clips with synced audio and plausible physics, and studios routinely route a scene across two or three of them. Around them sits a field of creative-media specialists worth recognizing: Midjourney and Black Forest Labs (the Flux models) for images, Runway, Pika, and Luma for video, Suno for music, ElevenLabs for voice, and Stability AI.
A newer frontier is world models — systems that simulate an interactive environment rather than describe one — which many researchers see as the path to physical intelligence. DeepMind's Genie 3 generates real-time, persistent 3D worlds; Fei-Fei Li's World Labs, which raised $1B in February 2026 from backers including AMD and NVIDIA, is building the same for simulation; and NVIDIA's Cosmos supplies world-model foundations to robotics developers. That connects directly to embodied AI, where "vision-language-action" models drive humanoid robots. The model-makers here — Physical Intelligence, Skild AI, and NVIDIA's GR00T — feed machines from Figure, which put around forty humanoids into a BMW plant at a $39B valuation, and Tesla's Optimus. Robotics startups raised roughly $8.5B in 2025.
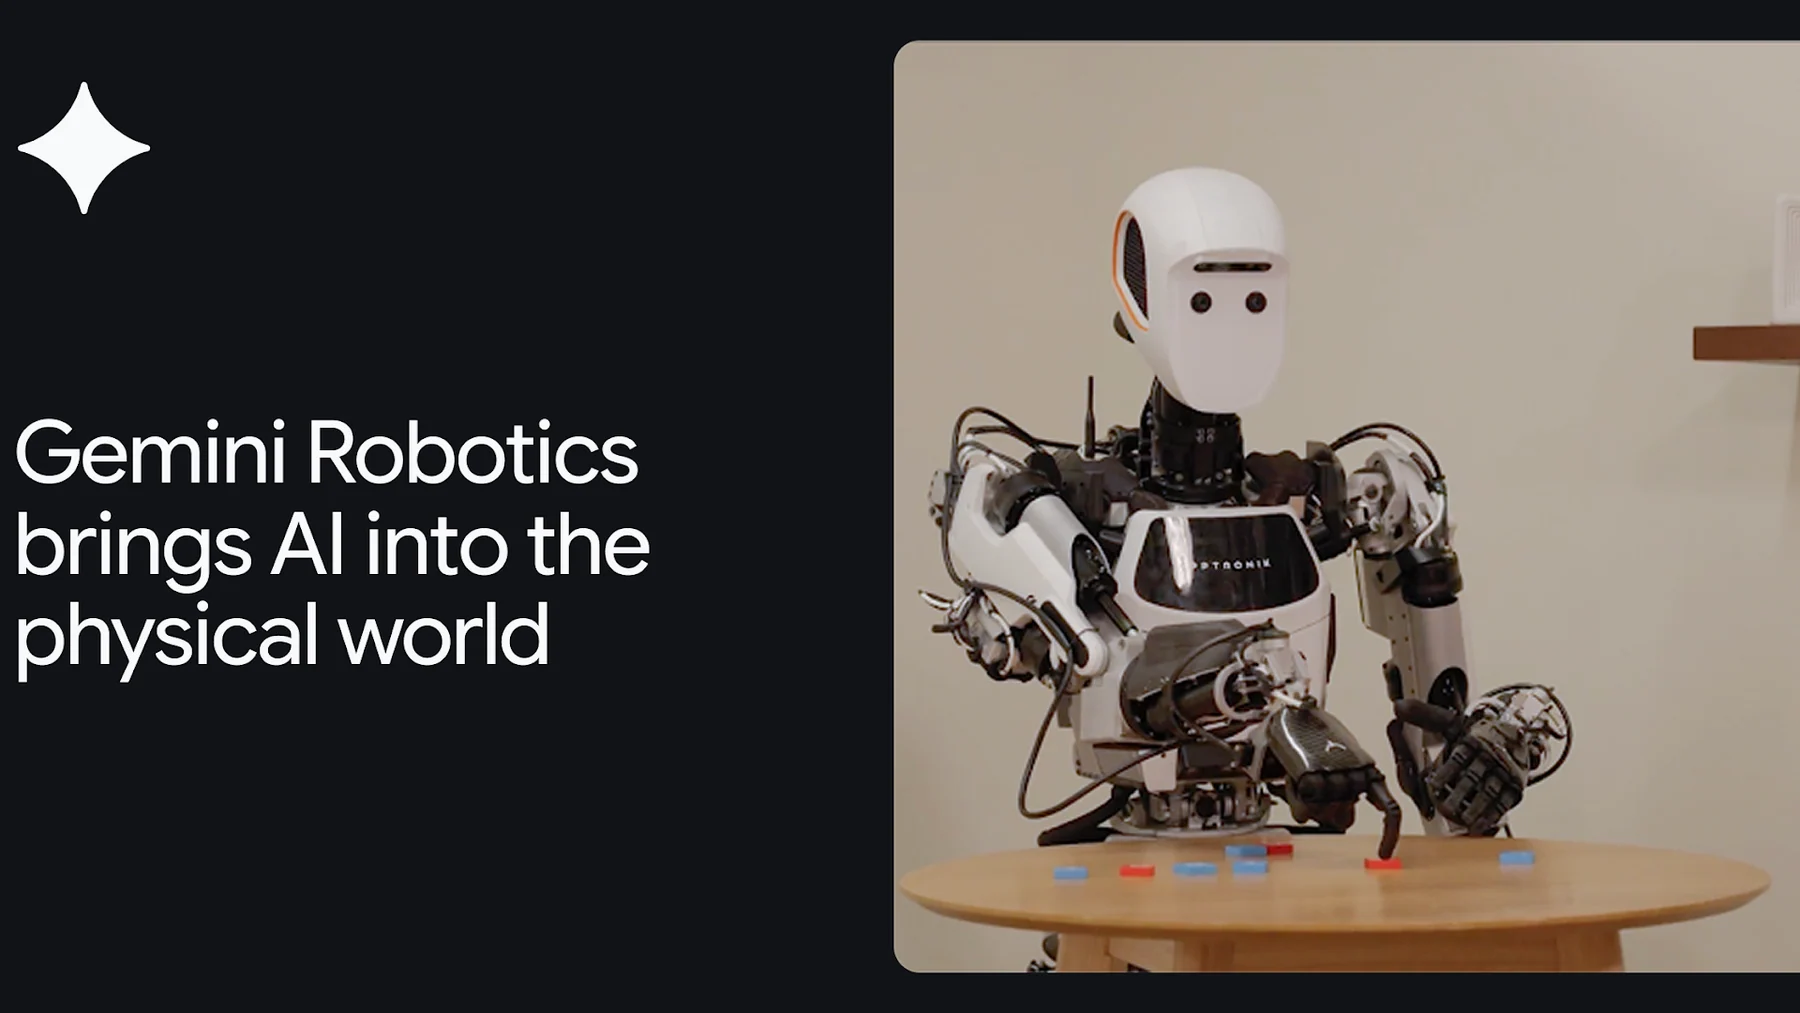
For an investor these adjacencies matter because they are the next compute driver: video and world-model training and inference are far heavier than text, so they extend the demand thesis of this whole layer. NVIDIA is the full-stack expression — its Cosmos, GR00T, and Omniverse tools make it a robotics-and-world-model play as much as a chip company — while most of the pure-plays (World Labs, Physical Intelligence, Figure, Runway, Kling via Kuaishou) are private or embedded in larger listed parents.
The next training constraint may be useful data, not raw volume
The quietest constraint in this layer is running out of things to learn from. The supply of high-quality human text is finite and largely exhausted — the "data wall" — which is pushing training toward two substitutes: synthetic data generated by models themselves, and reinforcement-learning "environments," interactive worlds in which a model practices a task against a verifiable reward. The post-training recipe has re-based from human-feedback tuning to reward-based methods plus synthetic self-play; essentially every recent frontier model uses a distinct variant.
This approach works best where rewards are verifiable—code that passes tests, mathematics with a checkable answer, or games with a score. It is riskier for open-ended language, where recursive training on model output can degrade the distribution. That distinction helps explain why recent gains have concentrated in coding, mathematics, and tool use. Mechanize, Prime Intellect, Mercor, and Surge are building environments and data for reinforcement learning, and The Information reported Anthropic leaders discussing more than $1B of spending on such environments over the coming year. This is a new input market, but valuations in the tens of billions require spending to convert into durable revenue.
Who may retain the profit
The evidence supports more confidence in aggregate infrastructure demand than in any standalone model business. Reasoning, agents, and video increase inference demand and the power, networking, and memory beneath it regardless of which lab leads a given month. That is a strategic demand conclusion, not a security recommendation; the decision layer separately tests valuation, equity capture, and downside.
The labs are the subtler call. OpenAI is the consumer franchise and Anthropic the enterprise and coding franchise, both reachable only through their backers — Microsoft, Amazon, Google, and Nvidia, detailed in Part V — and both worth owning for distribution and product rather than for model supremacy, because the middle of the model market is commoditizing underneath them at 5× to 100× lower prices. On the open-weight side, Alibaba is the strategically significant name, and the developer-token data suggests Chinese open models are winning a layer the US assumed it led, which makes Alibaba a real, if China-risk-laden, way to own the open frontier. The RL-environments vendors are an early, private, higher-risk expression of the data-wall trend. Throughout, the discipline is to treat the top benchmark score as noise and to treat enterprise API share, developer-token share, and token-efficiency as signal.
What would falsify the thesis
Three developments would change this assessment. A renewed pre-training acceleration—a much better model produced mainly by greater scale—would concentrate advantage among companies with the most compute. An efficiency shock larger than DeepSeek's could reduce near-term infrastructure demand faster than lower prices expand usage. Broad production adoption of reliable agents would pull enterprise revenue forward, supporting applications and the infrastructure behind them. The open-weight conclusion would also weaken if Meta and Alibaba materially retreat from open releases.
The quarterly reading order is more useful than a permanent model ranking. First compare price at a fixed level of capability; this shows how quickly intelligence is commoditizing. Next compare production usage and paid retention; this shows whether falling price is expanding the market. Then inspect inference cost and gross margin; this shows whether the provider keeps any efficiency gain. Finally, examine distribution and switching: consumer habit, enterprise integration, developer tooling, and the ability to route workloads among models.
The chapter’s conclusion has two levels. At the industry level, reasoning, multimodality, and agents can keep total compute demand growing even as each unit of compute becomes more efficient. At the company level, capability leadership is perishable and profit requires a control point beyond the model weights. Keeping those levels separate prevents the two most common mistakes in AI investing: assuming cheaper models make infrastructure unnecessary, and assuming the company with the best current benchmark automatically owns the economics.
Chapter 2.1 endnotes
Sources
Linked evidence for this chapter's figures and load-bearing claims: 6 7 8
Footnotes
-
2025: The State of Generative AI in the Enterprise. Menlo Ventures, 19 December 2025. Survey and bottom-up market estimate; not audited issuer revenue. ↩
-
Scaling AI for everyone. OpenAI, 27 February 2026. Company-reported product metric. ↩
-
Artificial Intelligence Index Report 2025. Stanford HAI, 7 April 2025. ↩
-
LLM inference prices have fallen rapidly but unequally across tasks. Epoch AI, 12 March 2025. ↩
-
Task-Completion Time Horizons of Frontier AI Models. METR, updated 8 May 2026. ↩
-
Model pricing snapshot. OpenRouter, undated; accessed 2026-07-25. ↩
-
Chinese AI models gain ground on U.S. rivals as low costs drive adoption. CNBC, 2026-07-07; accessed 2026-07-25. ↩
-
AI companies: revenue and valuation data. Epoch AI, 2026-07-21; accessed 2026-07-25. ↩